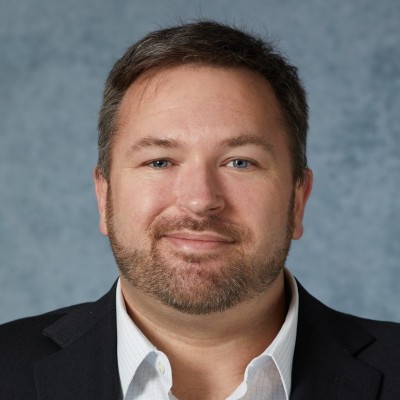
Ryan Urbanowicz
Research Scientist II Assistant Professor (Appointment Pending) Of Computational Biomedicine
West Hollywood, California, United States


Summary
👤
Senior🎓
Top SchoolRyan Urbanowicz is a computational biomedicine researcher and research scientist with a decade of experience building machine learning and data-mining methods for complex biological and epidemiological data. Trained in biological engineering at Cornell and genetics at Dartmouth, he developed the ExSTraCS learning classifier system to detect heterogeneous and epistatic patterns and was the first to solve the 135-bit multiplexer benchmark with that approach. He has held academic posts at Dartmouth, UPenn, and now Cedars-Sinai, where he combines algorithm development, data visualization, and teaching to translate methodological advances into biomedical discovery. Known for blending evolutionary computation with practical feature-selection and simulation strategies, he routinely tackles noisy, real-world datasets that challenge conventional models. Based in West Hollywood, he brings both hands-on research and classroom experience to interdisciplinary teams bridging AI and translational medicine.
 11 years of coding experience
 10 years of employment as a software developer
 PhD, Genetics, PhD, Genetics at Dartmouth CollegeM.Eng, Biological Engineering, M.Eng, Biological Engineering at Cornell University

Github Skills (43)
xcs10
feature-selection10
imputation10
classifier10
supervised-learning10
binary-classification10
data-science9
algorithms9
python9
scikit9
machine-learning9
partitioning9
optuna9
cython9
data-visualization9
Programming languages (3)
Github contributions (5)
UrbsLab/AutoMLPipe-BC
May 2021 - May 2022
An automated, rigorous, and largely scikit-learn based machine learning analysis pipeline for binary classification. Adopts current best practices to avoid bias, optimize performance, ensure replicatability, capture complex associations (e.g. interactions and heterogeneity), and enhance interpretability. Includes (1) exploratory analysis, (2) data cleaning, (3) partitioning, (4) scaling, (5) imputation, (6) filter-based feature selection, (7) collective feature selection, (8) modeling with 'optuna' hyperparameter optimization across 13 implemented ML algorithms (including three rule-based machine learning algorithms: ExSTraCS, XCS, and eLCS), (9) testing evaluations with 16 classification metrics, model feature importance estimation, (10) automatically saves all results, models, and publication-ready plots (including proposed composite feature importance plots), (11) non-parametric statistical comparisons across ML algorithms and analyzed datasets, and (12) automatically generated PDF summary reports.
Contributions:1 release, 128 commits, 23 pushes in 1 year
binary-classificationclassificationdata-cleaningfeature-selectionhyperparameter-optimization
UrbsLab/scikit-rebate
Aug 2024 - Jun 2026
A scikit-learn-compatible Python implementation of ReBATE, a suite of Relief-based feature selection algorithms for Machine Learning.
Contributions:3 releases, 6 pushes, 2 tags in 1 year 11 months
feature-selectionmachine-learningpythonscikit-learn
Find and Hire Top DevelopersWe’ve analyzed the programming source code of over 60 million software developers on GitHub and scored them by 50,000 skills. Sign-up on Prog,AI to search for software developers.